

Input$10.00
Cached$1.00
Output$50.00
Open a company for its current text models, the list rate per million tokens, and where to get the API. These are published list rates, not a bill we measured. Open the full rate notes.
 OpenAI
Standard rates for a prompt under 272,000 input tokens. Above that, OpenAI bills the whole request at twice the input and cache rates and 1.5 times the output rate. Batch and Flex are half of standard. Older models, including GPT-5.5, GPT-4o, and the o-series, are on OpenAI’s pricing page.
Input$10.00
Cached$1.00
Output$50.00
Input$2.00
Cached$0.10
Output$10.00
Input$1.00
Cached$0.05
Output$5.00
Input$0.10
Cached$0.01
Output$0.50
Input$2.00
Cached$0.20
Output$10.00
OpenAI says this promotional price lasts at least through 21 November 2026.
PHP patches two critical PHP2Shell flaws that AI helped researchers find and exploitInput$4.00
Cached$0.40
Output$20.00
Input$2.00
Cached$0.20
Output$12.00
Input$0.20
Cached$0.02
Output$1.20
 Anthropic
Global standard Claude API rates. US-only inference is 10 percent higher. Batch is half of standard. Cache writes cost more than a normal input; the table shows cache hits. Claude 4.7 and later use a tokenizer that Anthropic says produces about 30 percent more tokens for the same text.
Input$10.00
Cached$0.25
Output$50.00
Limited availability.
Chainguard opens a waitlist for Harness, a Claude Mythos 5.1 vulnerability hunterInput$10.00
Cached$0.25
Output$50.00
Input$4.00
Cached$0.20
Output$20.00
Input$2.00
Cached$0.10
Output$10.00
Prompts up to 100,000 tokens.
Inception launches Mercury 3, a diffusion LLM it says runs at 1,000 tokens per secondInput$0.10
Cached$0.01
Output$0.50
Prompts over 100,000 tokens.
Inception launches Mercury 3, a diffusion LLM it says runs at 1,000 tokens per secondInput$0.50
Cached$0.05
Output$2.50
Input$5.00
Cached$0.50
Output$25.00
Input$2.00
Cached$0.20
Output$10.00
Input$10.00
Cached$1.00
Output$50.00
Limited availability.
Claude used a free token to skip a fee on Georgia's election data hub, state confirmsInput$10.00
Cached$1.00
Output$50.00
Input$5.00
Cached$0.50
Output$25.00
Input$5.00
Cached$0.50
Output$25.00
Input$5.00
Cached$0.50
Output$25.00
Listed for prompts up to 200,000 tokens.
Input$5.00
Cached$0.50
Output$25.00
Input$3.00
Cached$0.30
Output$15.00
Input$3.00
Cached$0.30
Output$15.00
Input$1.00
Cached$0.10
Output$5.00
Retired, except on Bedrock and Google Cloud.
Input$15.00
Cached$1.50
Output$75.00
Retired, except on Google Cloud.
Input$15.00
Cached$1.50
Output$75.00
Retired, except on Bedrock and Google Cloud.
Input$3.00
Cached$0.30
Output$15.00
Retired, except on Google Cloud.
Input$0.80
Cached$0.08
Output$4.00
 Google
Paid Gemini API standard rates for text. Gemini output prices include thinking tokens. Batch is half of standard. Image, live, and audio models use different units and are on Google’s pricing page.
Through 30 November 2026. From 1 December 2026, Google lists $4 input, $0.20 cached, and $20 output. Not on the free tier.
Google DeepMind uses Gemini to push Lehmer's polynomial search to degree 2,000Input$2.00
Cached$0.10
Output$10.00
Prompts up to 200,000 tokens. Longer prompts are $4 input and $18 output.
Input$2.00
Cached$0.20
Output$12.00
Through 31 December 2026. From 1 January 2027, Google lists $1.50 input and $7.50 output.
Input$0.75
Cached$0.075
Output$3.75
Same introductory window as Gemini 3.8 Flash.
Google releases Nano Banana 2.1; our one-prompt test finds limits tooInput$0.75
Cached$0.075
Output$3.75
Text, image, video, and audio input share this rate.
Input$0.30
Cached$0.03
Output$2.50
Text, image, and video input. Audio input is $1.
Input$0.50
Cached$0.05
Output$3.00
Text, image, and video input. Audio input is $0.50.
Input$0.25
Cached$0.025
Output$1.50
Text, image, and video input. Audio input is $1.
Input$0.30
Cached$0.03
Output$2.50
 DeepSeek
Off-peak is half of peak. Peak hours are weekdays 01:00–04:00 and 06:00–10:00 UTC, except Chinese public holidays. The legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp are served by V4.1 Flash and billed at the Flash price. Search and Fetch are $0.75 per 1,000 successful requests.
Off-peak. Model name deepseek-flash, served by DeepSeek-V4.1-Flash-1017.
Exposed Cairn panels show one hacker's AI agents breaching more than 100 company sitesInput$0.15
Cached$0.003
Output$0.60
Peak hours.
Exposed Cairn panels show one hacker's AI agents breaching more than 100 company sitesInput$0.30
Cached$0.006
Output$1.20
Off-peak. Model name deepseek-v4-pro, version DeepSeek-V4-Pro-0813. No vision.
Input$0.66
Cached$0.022
Output$1.98
Peak hours.
Input$1.32
Cached$0.044
Output$3.96
 xAI
Global text rates for a prompt under 200,000 tokens. At that size, xAI bills every token in the request at double these rates. The US endpoint is 10 percent higher. Batch is 20 percent off these models except Grok Build 0.1. Image, video, and voice use other units.
500,000-token context.
GPT-6.1 Sol picks Democrats and Grok 4.7 picks Republicans when forced to name a candidateInput$2.00
Cached$0.50
Output$6.00
500,000-token context.
Input$2.00
Cached$0.50
Output$6.00
500,000-token context.
Input$2.00
Cached$0.30
Output$6.00
1 million-token context.
Input$1.25
Cached$0.20
Output$2.50
Reasoning and non-reasoning names are the same rate. 1 million-token context.
Input$1.25
Cached$0.20
Output$2.50
1 million-token context.
Input$1.25
Cached$0.20
Output$2.50
256,000-token context. No batch discount.
Input$1.00
Cached$0.20
Output$2.00
 Mistral
Standard rates for Mistral’s own text and code models. Cached input is the published cache-read rate. Z.ai models sold on this API, plus OCR, speech, and embeddings, are on Mistral’s pricing page.
Input$1.36
Cached$0.14
Output$4.18
Input$1.50
Cached$0.15
Output$7.50
Input$0.15
Cached$0.015
Output$0.60
Input$0.50
Cached$0.05
Output$1.50
Input$0.20
Cached$0.02
Output$0.20
Input$0.15
Cached$0.015
Output$0.15
Input$0.10
Cached$0.01
Output$0.10
Input$0.30
Cached$0.03
Output$0.90
Liquid AI released the LFM3 family, six open-weight models in the 2-billion-parameter class covering text, vision, audio, an omni model and a decision model, trained from one 1.7B base.
No single open-source coding model is best for every repository. A HumanEval score measures functional correctness on 164 handwritten problems, not your codebase.
OpenAI released GPT-6.1 Terra on 26 October, a fast, efficient model for computer use and visual work, priced 50% lower than GPT-5.6 Terra and GPT-6.1 Sol.
iFlytek's Spark X2.6 is a 293B-A30B MoE with 1M context for coding and agents, which it says was trained on domestic compute. A small Spark-X2.6-4B ships open under Apache 2.0.
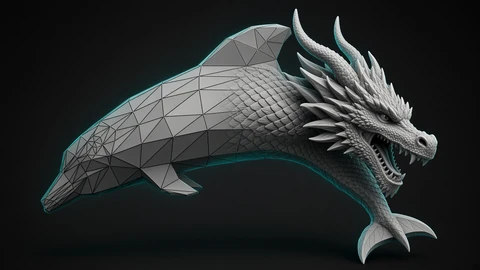
Hi3D has released code and weights for Hi3D v1.0, a model that turns a coarse 3D mesh and a photo into detailed geometry at up to 1536³. It reports a 90% 3D-printing slice rate, under a custom licence with branding rules.
Nanbeige's Apache 2.0 Nanbeige4.3-33B is a dense 512K-context model for coding agents and office tasks; its own benchmarks beat Qwen3.8-27B on most agent tests, not all.
fal post-trained Black Forest Labs' FLUX 3 into FLUX 3 Max, a hosted video model it says matches Seedance 2.5's preliminary arena rating while rendering about 22 times faster.
xAI's Grok Imagine posted a seven-minute first episode of a Homer's Odyssey series made with London studio Wonder Studios and director Dev Walker, the first step toward Elon Musk's promised AI film.
Shanghai AI Laboratory published the full Atria Dawn weights, a text-only agent model built on the 744B GLM-5.2, under the MIT License with a 512K context window.