Announced 19 Oct 2026 · Sources checked
What Metis Reasoning is
Thore Graepel, a former Google DeepMind research lead who was part of the team behind AlphaGo, has brought his new company, Metis Reasoning, out of stealth. Pathfounders reported the launch on 19 October 2026, and the London-based start-up published a white paper the same day setting out what it wants to build: AI systems that gather evidence, test hypotheses and check their conclusions before they commit to an answer.
The company's website describes its goal as AI that produces “conclusions and take[s] actions that are grounded, understood, and trusted,” aimed at high-stakes fields such as embodied AI, science and engineering where being wrong is expensive. Graepel told Pathfounders the idea in plainer words: “It knows what it knows. It knows what it doesn't know.”
Metis has not released a product, a model or any benchmark results. What it has published is an argument, a founding team and a claim that a working prototype exists. That makes this an early-stage launch to watch rather than a tool anyone can use today, and the details below come from the company's own paper and its founder's interviews.
Why Graepel thinks scaling is not enough
Graepel previewed his argument in an essay for MIT Technology Review on 2 October, in which he wrote that he had recently left DeepMind because he believed AI needed “a fresh approach to machine reasoning” drawing on AlphaGo's architecture. Pathfounders reports that he left Alphabet's research lab this summer. He is also chair of machine learning at University College London.
The white paper, The Age of Reasoning, lists three problems it says scaling cannot fix. Large language models produce confident falsehoods, a failure covered in our explainer on AI hallucinations. Their step-by-step reasoning traces often do not reflect how the answer was actually reached. And the knowledge a model relies on is stored invisibly in its weights, so users cannot inspect, edit or access-control it.
On the second point the paper cites research showing that chains of thought can omit the biases behind an answer, can be ignored by the model when it produces its final output, and become less coherent as tasks get harder. That fits other recent findings, such as models that keep reasoning even when told to stop. Graepel told Pathfounders that “more scaling will never give you an auditable reasoning trace that you can actually trust,” and called the fact that everything is stored in the weights the “original sin” of the transformer architecture.
The paper also makes an economic argument. It suggests that the gap between rapidly improving model capabilities and their modest measured effect on productivity may be partly a trust gap: businesses hesitate to let AI act for them when they cannot audit why it did something. It points to coding as the exception, because code is unusually easy to test, verify and roll back.
How the proposed system would reason
The proposed fix borrows AlphaGo's structure. The paper argues that AlphaGo's famous Move 37 against Lee Sedol in 2016 was not machine intuition: the system's policy network gave the move only about a one in ten thousand chance of being played by a human expert, and it emerged from an explicit search over possible futures. In that framing, today's language models resemble a powerful policy network, while the rest of the machinery that made AlphaGo work is missing.
Metis wants to add two pieces back. The first is an explicit, persistent epistemic state, a record of what the system holds as established, how certain it is, which hypotheses are still open and which have been ruled out. Claims can only change status when an independent judgment system decides the evidence warrants it, using formal checks, calculations or empirical evidence. When a premise is withdrawn, conclusions that depended on it must be reassessed, and the history records why.
The second is an objective for the reasoning itself: reducing uncertainty about the question at hand. Moves are chosen because they are expected to reduce that uncertainty over time, and the system can stop when the question is answered well enough, the budget runs out, or further inquiry is not worth the cost. It can also abstain, which the paper treats as a legitimate outcome rather than a failure.
To describe how reasoning proceeds, the paper uses the philosopher Jaakko Hintikka's interrogation game, which treats inquiry as a game between an inquirer and nature. A move might be asking a question, deriving a consequence, running a calculation or experiment, or challenging a premise. The paper walks through a medical example in which a doctor forms hypotheses, asks whether a feverish patient has a cough, orders a test and decides when the evidence is strong enough to act. Formal checking is part of the same family of ideas as the Lean-verified mathematics that labs have used to keep models honest in proofs.
Learning to reason, not just to answer
The paper separates two loops. In the inner loop, a single inquiry is played out with a fixed policy that proposes promising moves and a value function that estimates how much progress a position offers. In the outer loop, records of many completed inquiries, including failed and budget-limited ones, are used to train better policies and value functions, much as AlphaGo and AlphaZero improved through self-play.
An important design choice is that the learned parts cannot overrule the evidence rules. The paper says a policy may learn to play better, but it cannot make an unsupported claim count as progress merely by assigning it a high value. The aim is a system that becomes better at deciding which question to ask next, which sources are reliable for which claims and which challenges expose hidden errors.
Metis calls this a new scaling axis. Because knowledge is kept separately from the reasoning process, the paper argues, facts can be updated, removed or access-controlled without retraining, verified knowledge can accumulate and be reused, and many small reasoning steps need not be run by large, expensive neural models. If that holds, it could cut inference costs and let capable reasoning run on edge devices or robots. These are stated benefits of the design, not measured results.
Graepel acknowledged to Pathfounders that the approach broadly falls within neuro-symbolic AI, which pairs neural networks with explicit symbolic structure. Metis does not abandon neural networks: it would use them to interpret language and images and to propose moves, while the structure around them keeps score.
Who is behind it and what exists so far
The white paper lists four authors, who are also the founding team named by Pathfounders. Alongside Graepel are Piers Ingram, a technology and biotech entrepreneur whose ventures have raised more than US$350 million according to Pathfounders; Michael Warren, a robotics and autonomous systems specialist with experience at DARPA, Boeing and GM; and David Berman, head of AI at Cambridge Consultants and an adviser to NATO and the UK government. The paper gives the company's locations as London, Singapore and Los Angeles, and Pathfounders says it is building its operations around London's King's Cross AI cluster.
Graepel said Metis has “a prototype that can reason about PhD-level scientific problems,” and that scientists connected to the founders' biotechnology ventures have tested it. He expects an “industry-hardened” system to be ready for external testing within three to six months. Robotics is another priority; “robotics is a reasoning problem,” he said.
Funding is not disclosed. Pathfounders, citing a Bloomberg report, says Graepel is seeking to raise tens of millions of dollars, and he confirmed that fundraising discussions are ongoing without giving figures. EU-Startups News describes the company as pre-seed. The founder's track record will help: Pathfounders notes that other AlphaGo veterans have raised large sums for their own start-ups.
What to watch and what is still unproven
The obvious caveat is that nothing has been shown publicly. There is no demo, no paper with experiments and no benchmark, and Pathfounders points out that the company has yet to publish independent results backing its claimed advantages. Claims about lower hallucination rates, auditability and cheaper inference all come from the design argument rather than from tests.
The hard part is also the part the paper discusses least concretely. Go has a complete board and fixed rules; the open world does not. The paper itself notes that real inquiry starts from partial observations, that evidence can be costly, that useful moves may have to be invented and that some questions have no answer. Building a judgment system that reliably decides what the evidence warrants, across messy domains, is a research problem in its own right. Robotics start-ups such as Aether AI with its causal robotic system are pursuing related ideas about explicit world knowledge, and none has yet shown it beats scaled-up models in the open world.
Still, the bet is clear and testable. If Metis opens its system to outside testers in the three to six months Graepel suggests, the first questions will be whether its reasoning traces are genuinely faithful, whether it abstains when it should, and whether it is any cheaper than a frontier model doing the same work.
Common questions
Can I try Metis Reasoning's AI?
Not yet. Graepel told Pathfounders that an industry-hardened system should be available for external testing within three to six months; for now the company only takes enquiries.
How is Metis different from reasoning models like those from OpenAI or Anthropic?
Those models reason in generated text, with knowledge stored in their weights. Metis proposes keeping knowledge in an explicit, editable record and only updating it when an independent check says the evidence supports the change.
How much money has Metis raised?
It has not said. Pathfounders, citing Bloomberg, reports that Graepel is seeking tens of millions of dollars, and EU-Startups describes the company as pre-seed.
Sources & further reading
- AlphaGo co-creator comes out of stealth with startup to kill hallucinations and agentic overreach ↗
- The Age of Reasoning (white paper) ↗
- Metis Reasoning: Intelligence from first principles ↗
- Don't be fooled: LLMs don't reason ↗
- Former DeepMind Researcher Launches Metis Reasoning to Advance AI Capabilities ↗
How this story was made
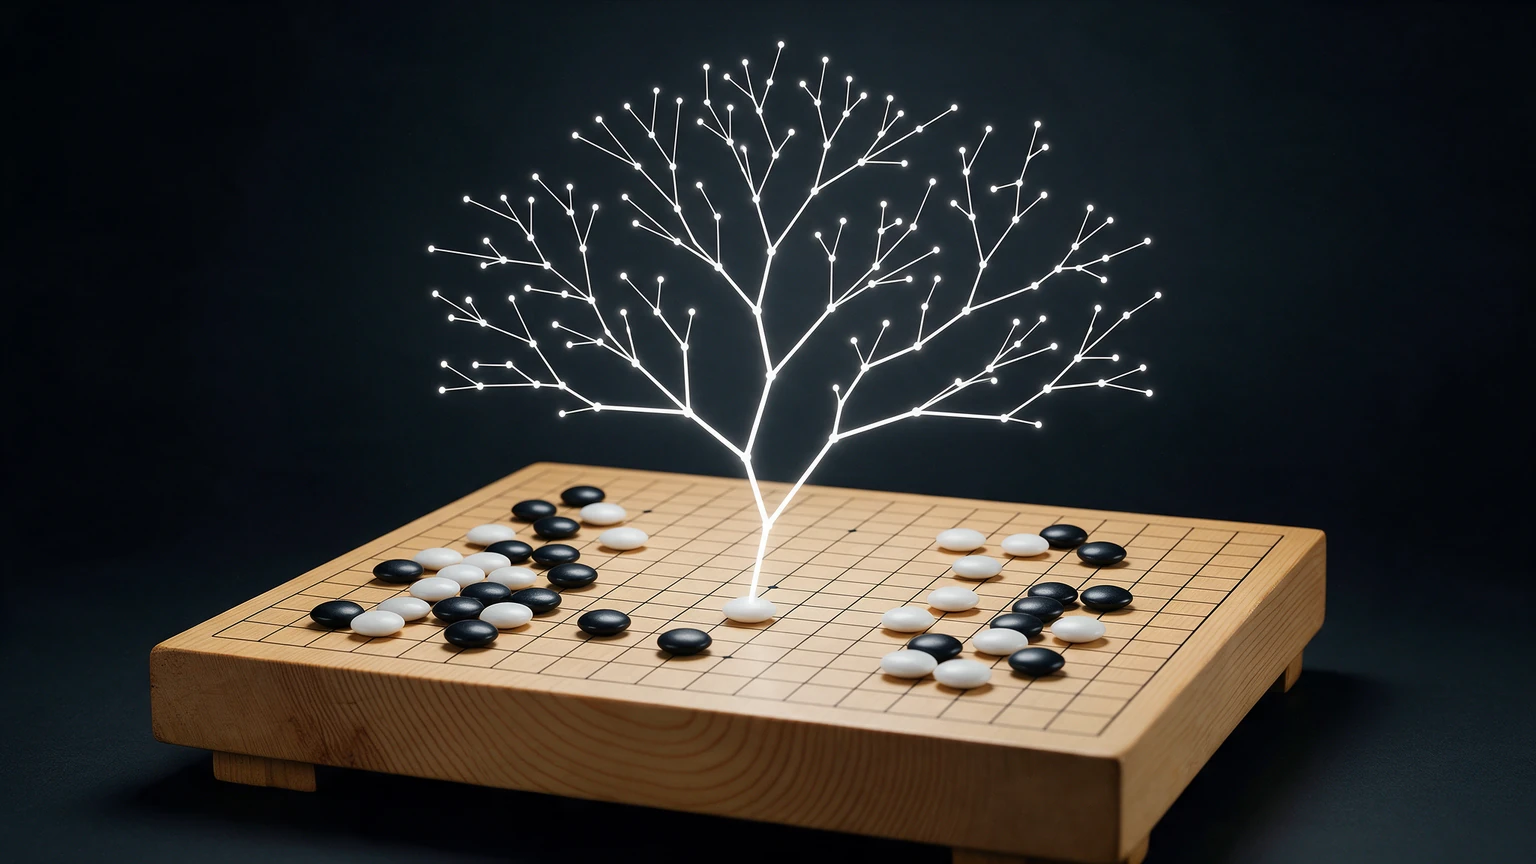
Written by Kristian Kostov with AI assistance and checked against the linked sources. Company performance claims are attributed to the company. Analysis reflects AiLookout’s interpretation; we have not independently tested the products discussed. The cover is an AI-generated editorial illustration, not a photograph or evidence of an actual event.
Our editorial standards