Announced 21 Oct 2026 · Sources checked
What Berget AI released
Swedish AI inference provider Berget AI on 21 October 2026 published an open-source method for calculating the carbon emissions of every individual AI request, not just an average per model or per data centre. The code and the full methodology are on GitHub under the MIT licence, the calculation library is on npm as @bergetai/co2-calculator, and a public calculator at co2.berget.ai applies it to a choice of models, hardware and regions.
The method was developed with researchers at the Stockholm Environment Institute (SEI), which the partners describe as the knowledge partner, with the US non-profit WattTime as scientific partner and the Swedish climate-data platform Klimatkollen as a further partner. According to Berget AI, the partners mapped and measured the energy, water and hardware footprint of Berget's own infrastructure, as well as the footprint of Klimatkollen's Garbo AI service, which runs on it, and combined those measurements with published research on converting them into emissions.
Berget AI, founded in Sweden in 2024, sells inference and AI infrastructure to private and public sector customers and says it has shown the CO2 emissions of each API request in its console since 2025. What is new is that the method behind those figures is now public, so other providers can run it on their own hardware and outsiders can check the assumptions. The company says that, as far as it knows, it is the first inference provider to calculate emissions per request on its own infrastructure and publish how.
Where the 8.5 times figure comes from
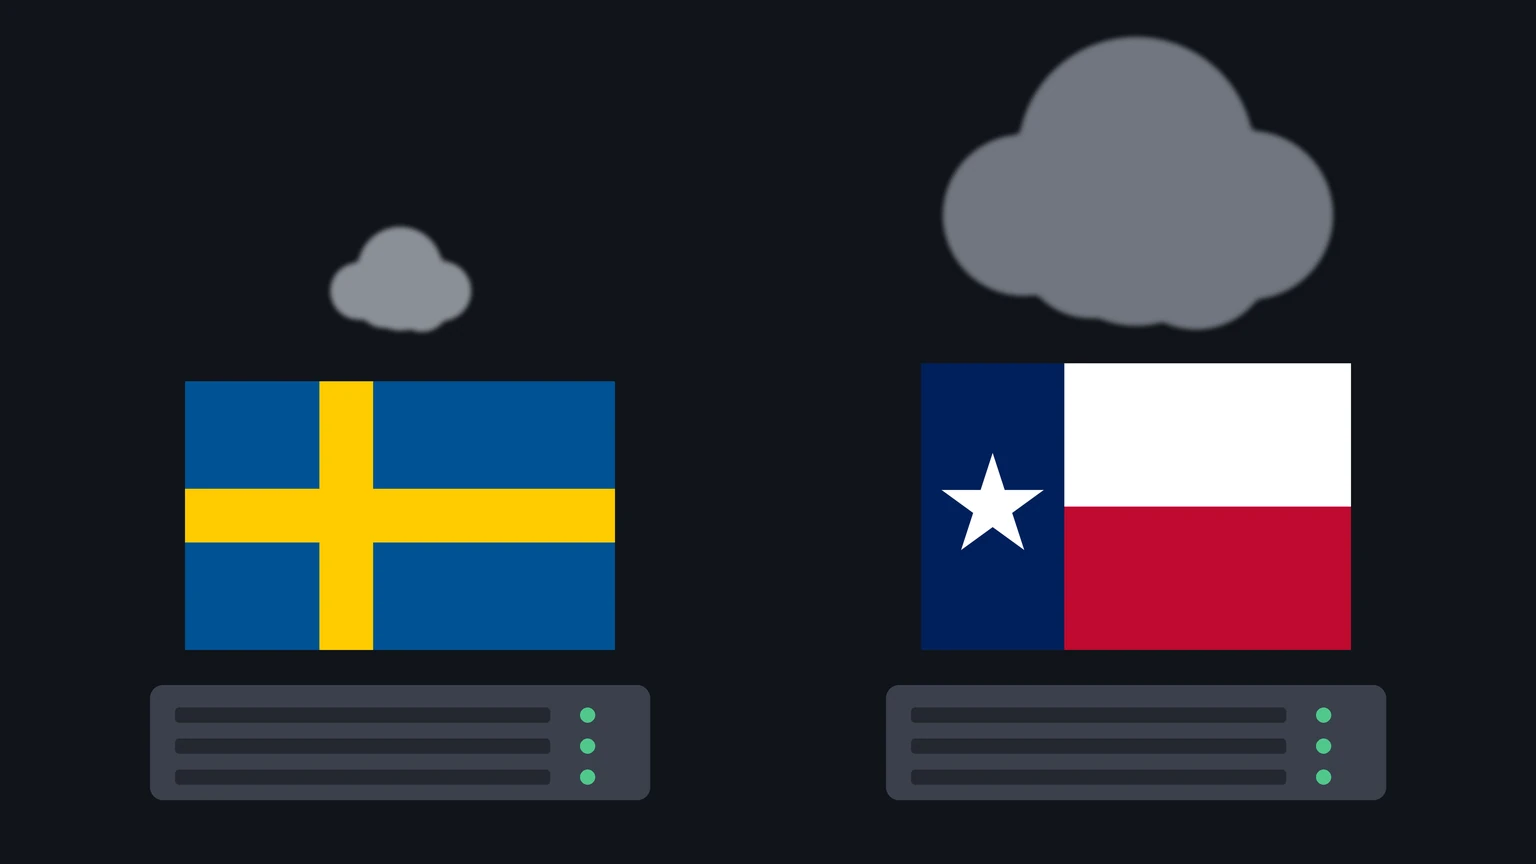
The headline example is a single typical request to Kimi K3, Moonshot AI's large open-weight model, which many providers now serve themselves (we covered recent work to speed up Kimi K3 inference on NVIDIA GB300). On identical hardware, Berget AI's corrected release puts that request at about 0.4 grams of CO2 in Sweden, 1.6 grams in Ireland, 2.5 grams in Germany and 3.2 grams in Texas, so roughly 8.5 times more in Texas than in Sweden.
The fact sheet gives the setup: version 1.1.1 of the calculator, an NVIDIA B300 node on a shared deployment, a production-typical request of 5,000 input tokens and 387 output tokens, weighted by a typical day's traffic. Energy use is about 4 watt-hours in both places. The difference comes from the grid and the cooling: the release lists average grid intensity of about 8 grams of CO2 equivalent per kilowatt-hour for Sweden (IEA 2024), 224 for Ireland (SEAI 2024), 337 for Germany (Ember 2024) and 333 for the Texas ERCOT grid (EPA eGRID 2023), against a global average near 470.
The breakdown is revealing. In Sweden, 89 percent of the 0.38 grams comes from manufacturing the hardware, because the electricity is almost carbon-free. In Texas, 90 percent of the 3.2 grams comes from electricity, and the request also uses about 6 millilitres of cooling water. Put differently, the embodied share is roughly the same third of a gram in both places; the gap is almost entirely the grid. The release does not show every intermediate step, and the per-kilowatt-hour figures and the 4 watt-hour estimate alone do not reproduce the totals, because the package also applies cooling overhead and time-of-day weighting. Anyone who wants to check the numbers should run the published code.
A correction on launch day
The figures changed on launch day. An earlier version of the release, sent to journalists under embargo, said a request emitted 1.2 grams in Ireland, 2.1 in Germany and 3.9 in Texas, and that Texas was ten times worse than Sweden. Berget AI says a source review corrected the grid intensities, which lowered the Texas figure to 3.2 grams and the ratio to 8.5 times. Sweden's figure did not change. When we read it on 21 October, SEI's own press release still carried the earlier ten-fold headline and the uncorrected numbers, so readers may see both versions in coverage.
The correction does not change the direction of the finding, but it is a useful reminder of how sensitive these totals are to a single input. Swapping one year's grid figure for another moved the Texas result by almost a fifth.
How the calculator counts a single request
The calculator follows the Green Software Foundation's SCI for AI specification and adds up several parts for each request: GPU energy while the request runs, a share of the GPUs' idle draw, the server chassis, cooling overhead, and an amortised share of the emissions from manufacturing the hardware. The methodology document, now at version 3.2, explains each step and the measurements behind it.
Several choices stand out. Berget AI pulls GPU time, output tokens, concurrency and prompt-cache hit rates for the models it runs from its own production metrics rather than estimating them, and publishes the per-model aggregates in the repository. It derives concurrency from request rate and latency because the serving software's own counter overstated it badly; for its busiest model, the document says about 98 requests were reported running when about 6.7 was the real figure. Cached prompt tokens are counted as cheaper, since they skip part of the computation.
Hardware that sits idle still uses power, and the method charges that standby energy to requests. The release says an idle B300 still draws 236 watts, measured over seven days in production, while the methodology reports about 122 watts per GPU at zero load over a 24-hour window; the two documents do not explain the difference. Manufacturing is set at about 1,000 kilograms of CO2 per data-centre GPU, with refurbished hardware counted as zero, and an uncertainty of 30 to 50 percent because NVIDIA and AMD do not publish per-GPU life-cycle figures. Cooling is modelled by climate: free-air cooling in the Nordics at a power usage effectiveness of about 1.15 with no water, rising toward 1.8 and up to two litres of water per kilowatt-hour in hot regions.
The document also records a bug fix. An earlier version divided a node's fixed costs by the number of requests running at that instant, so a single request at night could carry up to about 21 times its fair share. Fixed costs are now spread over the day's average load.
Who can use it
The library is written in TypeScript and ships with preset profiles: 14 models including Llama, Mistral, Gemma, GLM, Kimi K3 and Whisper; 15 grid regions from Sweden and Quebec to India and Poland; and seven hardware configurations from NVIDIA B300, H100, H200, A100 and L4 servers to AMD MI300X. Providers can define their own hardware, data-centre locations and fine-tuned models, and the repository includes integration examples for web services and monitoring.
For models Berget AI does not operate, such as closed frontier models from Anthropic, OpenAI and Google, there are no production measurements, and the document says their parameters remain estimates taken from the outside-in EcoLogits model. That is the main limit for buyers who mostly use closed APIs: the method is designed to be run by the party that owns the hardware, and only that party has the metrics that make it more accurate than an estimate.
Why per-request numbers matter for buyers
Berget AI's argument is commercial as well as environmental. Chief executive Andreas Lundmark said most companies have no way of knowing what their AI use emits and that most European buyers would choose differently if they could see the numbers. Chief technology officer Christian Landgren said most alarming figures about AI's footprint come from multiplying an average by a guess at volume, and that the only fair comparison is to calculate each request and add them up. SEI research director Somya Joshi pointed to the International Energy Agency's projection that data-centre electricity use will more than double to about 945 terawatt-hours by 2030, with AI as the main driver.
The pitch relies on open-weight models, which can run in any data centre, so the buyer can choose where a request is served. Berget AI cites 29 percent of tokens on Vercel's AI Gateway in June 2026, up from about 11 percent in April. That figure is already dated: Vercel's own October production index put open-weight models at 71.5 percent of gateway tokens in September. Location also matters for capacity, as grid limits in places such as Essex, where Microsoft dropped a planned Nscale data centre, have shown. A seller in a low-carbon grid has an obvious interest in publishing figures like these, which is why the open code matters more than the headline ratio.
What the method leaves out
The figures are location-based, using each grid's average mix. The release says marginal emission rates, which estimate the effect of extra demand on which power plants run and what gets built, will be added to the calculator next month and may significantly change the result for Swedish data centres. Training is excluded by default because self-reported training figures vary by about 50 percent and are often not comparable between open and closed models. The current version also does not include the water and energy footprint of chip manufacturing, which the partners say they plan to add.
The methodology lists its own uncertainties: measured GPU power can differ from rated power by 20 to 40 percent, embodied carbon relies on proxy data, and the concurrency model is an empirical fit. No independent group has yet audited the method or reproduced the Kimi K3 example, and Berget AI's Gemma 4 31B example in the repository shows how much framing matters: operational emissions are about 57 times lower in Sweden than the US average, but only about 7 times lower once manufacturing is counted.
Common questions
Is the 8.5 times figure independently verified?
No. It is Berget AI's own calculation for one Kimi K3 request with stated settings. The code is public, but no outside group has published a reproduction yet.
Does the number include training the model?
No. Training is excluded by default because published training figures vary widely. The package has an option to include an amortised training share.
Can I see emissions for ChatGPT or Claude this way?
Only as estimates. Berget AI has no production data for closed models, so their profiles rely on the outside-in EcoLogits model.
Sources & further reading
- New open-source method shows the same AI request emits 8.5 times more CO₂ in Texas than in Sweden ↗
- New open-source method shows the same AI request emits ten times more CO₂ in Texas than in Sweden ↗
- CO₂ Impact Calculator for AI Inference (README) ↗
- Methodology: AI CO₂ Impact Calculator for Berget AI (version 3.2) ↗
How this story was made
Written by Kristian Kostov with AI assistance and checked against the linked sources. Company performance claims are attributed to the company. Analysis reflects AiLookout’s interpretation; we have not independently tested the products discussed. The cover places the companies’ own logos, taken from public-domain or openly licensed files credited in the caption, on a plain background. It is not a product photograph, a screenshot, or an endorsement.
Our editorial standards