Announced 23 Oct 2026 · Sources checked
What the modules do
An open-source Linux kernel module called gpu-unlock has become one of the most talked-about hardware projects among people who run AI models at home. Published on GitHub by the developer Zagitta, it raises the rate at which NVIDIA GeForce RTX 30-series cards issue one specific kind of Tensor Core instruction: FP16 and BF16 matrix math that accumulates results in FP32, the format most training and inference code uses for mixed-precision work. The project describes the goal as unlocking that instruction issue rate "to their professional equivalents".
The repository was created on 18 October 2026 and had about 2,800 stars when we checked it on 25 October. On 23 October a second developer, publishing as JustAResearcher, released gpu-unlock-ada, a fork that ports the same approach to the RTX 4090 and, experimentally, to one RTX 4070 Ti Super. Its README reports FP16 and BF16 throughput with FP32 accumulation roughly doubling on a single tested RTX 4090.
Neither project changes the card's firmware permanently, flashes a new VBIOS or patches NVIDIA's driver. Both run at boot, before the stock NVIDIA driver takes the card, and both stop doing anything once their kernel parameter is removed. We found no public statement from NVIDIA about either project.
Why GeForce cards ran this math at half speed
GeForce cards and their workstation counterparts often share the same silicon. The gpu-unlock README says consumer Ampere chips run FP16 and BF16 fused multiply-add into FP32 at half the instruction issue speed, and that the module doubles that issue speed on GA102, GA103, GA104 and GA106 chips, the dies behind cards from the RTX 3060 to the RTX 3090 Ti.
The RTX 4090 report in the Ada fork shows the same pattern clearly. Before the unlock, its benchmark measured about 306 to 326 trillion operations per second for FP16 math that also accumulates in FP16, but only 165.6 for FP16 into FP32 and 165.5 for BF16 into FP32. After the unlock, the FP32-accumulate modes measured 331.6 and 330.6, in line with the FP16-accumulate rate. INT8, the older dp4a instruction and ordinary FP32 math stayed where they were, according to the RTX 4090 technical report.
In other words, the hardware was already capable of the faster rate for one accumulation mode and held to half speed for another. The modules flip that setting for the mode that matters most to machine learning frameworks.
How the unlock works
The mechanism is a set of speed-select registers on the GPU. According to the gpu-unlock README, the module combines a technique first developed for NVIDIA's CMP mining cards with the early timing of an earlier UEFI-based unlock. It runs an unlock sequence on the card's own firmware processor, writes new values into two speed selectors, then performs a PCIe function-level reset before the unmodified NVIDIA driver binds to the card.
Timing is the whole trick. Loading the module by hand after the NVIDIA driver has taken a card does nothing, so the packages place gpu_unlock in the initramfs and insert it just ahead of the nvidia module. The author says this design avoids patching NVIDIA's driver again every time a new version ships, which was the main drawback of earlier approaches.
Each build downloads pinned NVIDIA and CachyOS inputs over HTTPS, checks their SHA-256 hashes and generates the firmware payload locally. The source archives and packages do not ship NVIDIA archives or generated firmware. The kernel module and packaging are licensed GPL-2.0-only, while NVIDIA firmware stays under NVIDIA's own terms.
What changes, and what does not
The headline number in the gpu-unlock README comes from an RTX 3090 Ti running a dense 8,192-cubed matrix multiplication at 450 watts with FP32 accumulation. BF16 went from 87.50 to 157.41 TFLOPS, FP16 from 87.46 to 118.39 TFLOPS, and TF32 from 42.58 to 82.61 TFLOPS, using five-sample medians.
A compatibility table built from user reports lists BF16 matrix-multiply gains of 68 to 80 percent on the RTX 3090 Ti, 25 to 67 percent on the RTX 3090, 70 to 73 percent on a 10 GB RTX 3080, 73 to 81 percent on the RTX 3070 and about 80 percent on a 12 GB RTX 3060. One OEM RTX 3080 Ti completed the unlock but stayed at half rate. The README warns that these figures come from each reporter's own benchmark and are not directly comparable, and that power limits matter: the lowest result, 25 percent, came from cards capped at 225 watts.
Real workloads gain less than raw matrix math. The README cites LLM prefill, the step that processes a prompt, speeding up by 14 to 36 percent in four reports, along with gains in diffusion image generation and FlashAttention. Token-by-token LLM decoding, which is limited by memory bandwidth rather than math, and INT8 work stay about the same. Reports that compared outputs found them bit-identical before and after the unlock.
That split matters for anyone deciding whether to try it. Image generation, fine-tuning and long-prompt processing lean on exactly the instructions the module speeds up. Chatting with a local model is mostly decoding, where the gain is small. The same logic explains why optimised kernels such as FlashAttention benefit: they keep the Tensor Cores busy instead of waiting on memory.
The RTX 4090 and 4070 Ti Super fork
The Ada fork, version 1.1.1, credits a payload and analysis published on Hugging Face as TOTORONG/AD103_win_unlocker, and builds its Linux loader and boot packaging on Zagitta's module. Its report says plainly that it does not claim original discovery of the RTX 4090 unlock chain.
The evidence is thinner than for the RTX 30 cards. The RTX 4090 result is one physical card and one successful cold power-on, demonstrated on 23 October with NVIDIA driver 615.78.08. The benchmark measures instruction issue rates with operands held in registers, not an end-to-end matrix multiply or an application, and it does not compare numerical results with a reference. The author lists independent cold-boot reproduction and numerical validation as still pending, and notes that the cleaned-up module published in the repository has not yet had its own hardware confirmation.
A separate test on one RTX 4070 Ti Super under a 240-watt cap measured FP16 and BF16 with FP32 accumulation rising from 95.0 to about 190 TFLOPS, and TF32 from 47.49 to 94.51. A verified FP8 matrix multiply on the same card showed only a 0.3 percent difference. That card needs an extra experimental flag and its exact PCI address, and other Ada cards are rejected.
Installing it, and undoing it
Installation is a git clone followed by make install, which detects Arch, Debian and Ubuntu, or Fedora and RHEL families and builds a native package. The user then adds gpu_unlock.targets=all, or the exact PCI address of one card, to the kernel command line. Nothing happens without that opt-in. Reports on the RTX 30 module cover machines with up to four cards, the card that drives the display, and cards passed through to a virtual machine.
The display card goes blank briefly during boot while the reset happens. Suspend to RAM powers the cards off and resets the selectors, so the module unlocks them again on resume, adding about a second. Hibernation is not covered. For the Ada fork, the author tells users to power the machine fully off before the first attempt, because a warm reboot may not leave the card in the fresh state the sequence needs.
Undoing it is simple: remove the kernel parameter, or delete it for a single boot in the bootloader, and remove the packages to take out the module entirely. The Ada README recommends keeping an unmodified stock boot entry available.
Risks and open questions
This is low-level hardware work by independent developers, not a supported NVIDIA feature. Both READMEs describe failure modes, such as firmware that never stops, in which the module deliberately keeps memory buffers until the machine is powered off. Windows support exists only through separate experimental ports, and the gpu-unlock module itself is Linux-only.
There are also questions these sources do not answer. NVIDIA has not commented, so nothing is known about how future drivers or firmware will treat cards that have been unlocked, or how warranty terms might apply. Heat and power draw under sustained full-rate Tensor Core work are not documented beyond the telemetry in the RTX 4090 report. And because most results are self-reported, the true gain on any given card, cooler and power limit will vary.
AI Lookout did not install or test either module. All figures above are the projects' own measurements or user reports collected in the README.
Who it is for
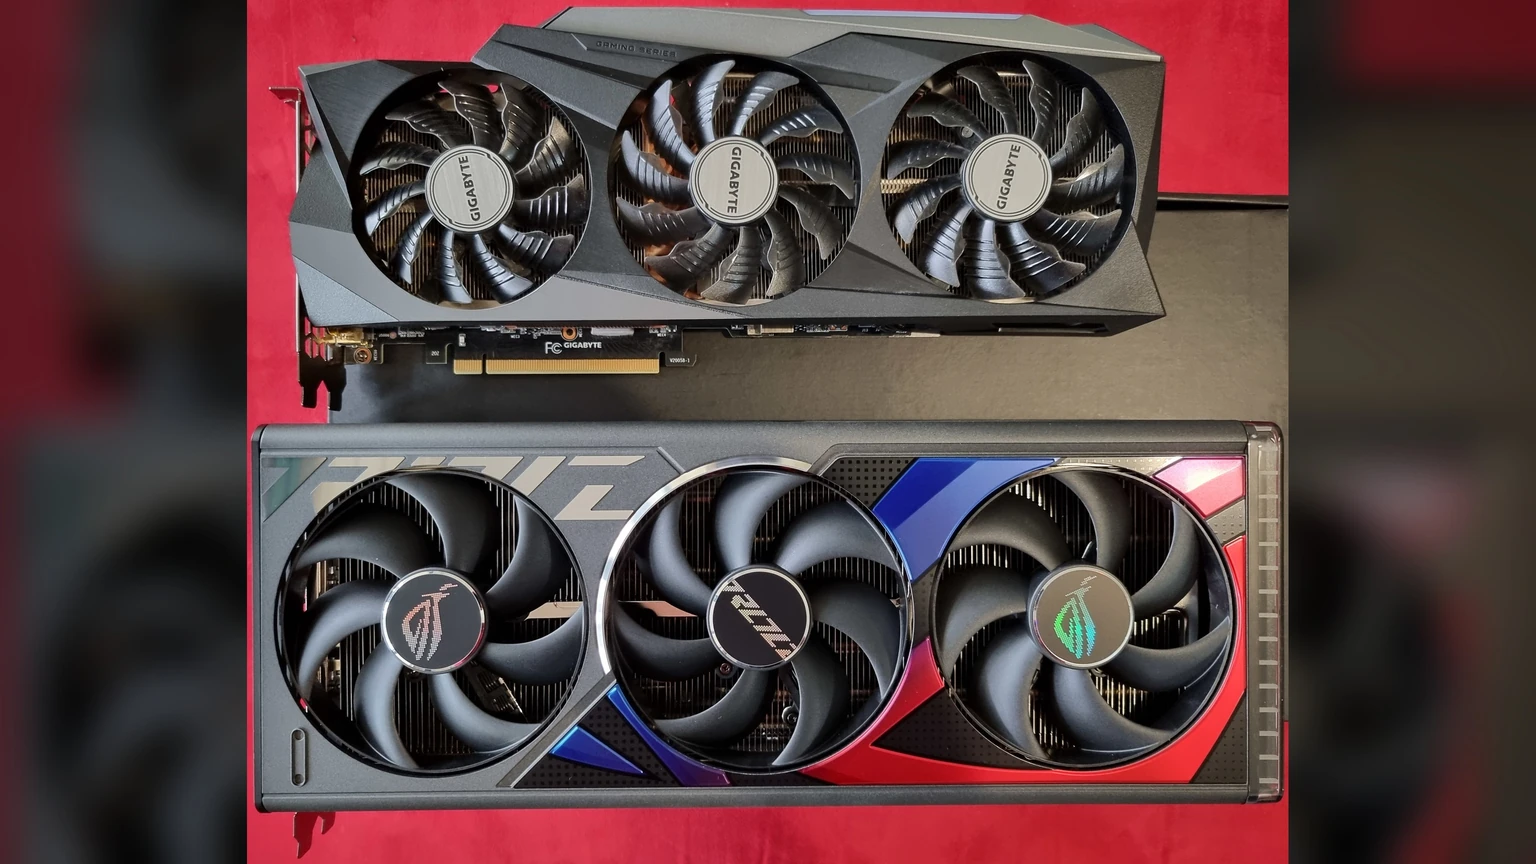
The audience is clear: people training or running models on used RTX 3090s and RTX 4090s, a popular choice for home AI because of their 24 GB of memory. For them a free software change that speeds up prefill, diffusion and fine-tuning is significant, especially while newer local AI hardware such as NVIDIA's RTX Spark laptops is just reaching buyers. Open models are increasingly pitched at exactly this class of card, from Tencent's Hy-Nomas world model with its single RTX 4090 mode to Black Forest Labs' smaller FLUX image model, and hobby research such as the Warcraft III agent trained on one desktop runs on the same machines.
Anyone comfortable with Linux kernel parameters and initramfs tools can try it and roll it back. Anyone who cannot afford downtime on a working machine should wait for more independent reproductions, particularly on the RTX 4090.
Common questions
Does gpu-unlock make games faster?
The projects document gains in Tensor Core matrix math used by AI workloads. They do not report gaming gains, and ordinary FP32 shader math was unchanged in the RTX 4090 test.
Is the unlock permanent?
No. It runs at each boot only when the kernel parameter is set. Removing the parameter or the packages and powering off returns the card to its stock state.
Does it work on Windows?
The gpu-unlock module is Linux-only. Separate experimental UEFI-based ports exist, but they are not part of these repositories.
Sources & further reading
How this story was made
Written by Kristian Kostov with AI assistance and checked against the linked sources. Company performance claims are attributed to the company. Analysis reflects AiLookout’s interpretation; we have not independently tested the products discussed. Cover photography is illustrative and does not depict the specific announcement or product.
Our editorial standards